A founder's inbox mixes bugs, pricing questions and feature requests. Someone needs to triage them before a support reply goes out. As of November 16, 2026, Vercel's official AI Gateway model page lists Tencent Hy4 Flash as a new option to test that workflow. The useful question is whether it reliably classifies your own messages at an acceptable cost, rather than whether its promotional token price looks attractive in isolation.
What the listing confirms
The model ID is tencent/hy4-flash. Vercel shows access through AI SDK and its compatible API formats, a listed release date of November 16, 2026, a context window up to 1 million tokens and a 64,000-token maximum output. The page describes reasoning, tool calling, structured output, prompt caching and image understanding. These are published capability claims, not independent SoyJB measurements.
The visible rate at the time of this check is $0.04 per million input tokens and $0.14 per million output tokens, marked 50% off. Vercel's November 16 announcement says the introductory discount applies to input, cached input and output tokens through November 29, 2026. It does not give a publication hour. Check the live rate before routing production volume because pricing can change after the promotion. Requests are billed to your AI Gateway team and subject to Tencent Cloud's linked terms and privacy policy.
A small evaluation you can run this week
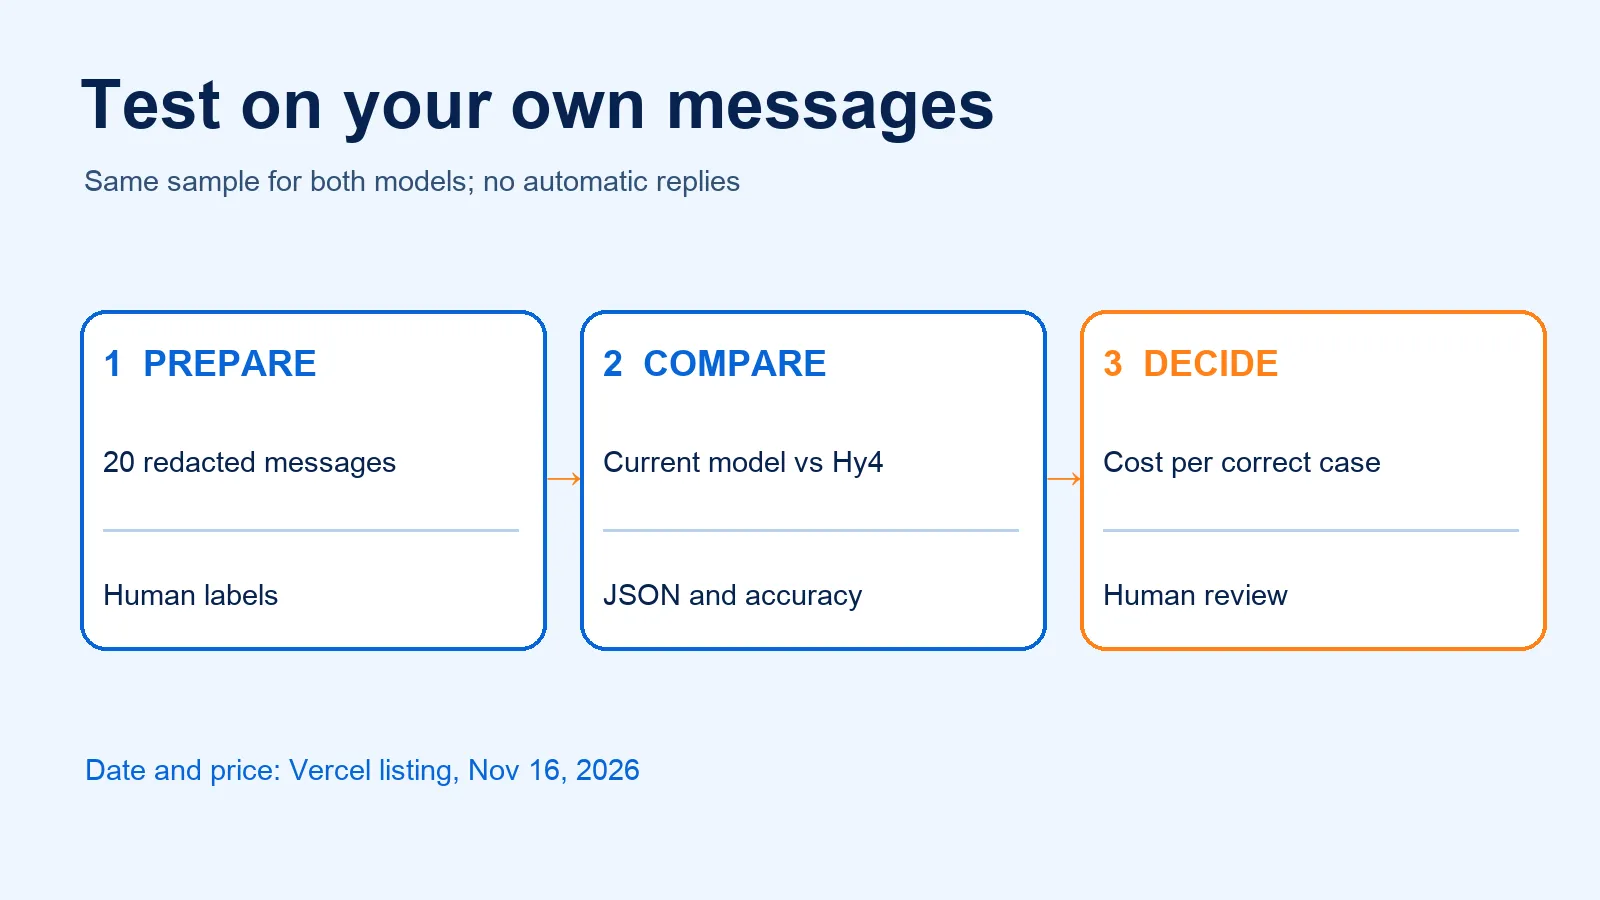
Take twenty real customer messages, remove names, email addresses and sensitive details, then hand-label each as bug, pricing, request or other. Record which ones are actually urgent. Run the same set through your current model and Hy4 Flash using one fixed instruction:
Classify this customer message. Return only JSON with type (bug|pricing|request|other), priority (high|medium|low), and summary (15 words maximum). Do not invent facts. If the message lacks enough information, choose other and explain the uncertainty in summary. Message: {{REDACTED_MESSAGE}}Vercel's AI SDK example uses generateText({ model: 'tencent/hy4-flash', prompt: ... }) and a server-side AI_GATEWAY_API_KEY. Keep that key out of the browser. Parse and validate each JSON response before inserting it into a ticket system. Published support for structured output does not replace application validation, especially when the model is handling messy, multilingual customer input.
For each message, record the category match, false urgency, unsupported claims and whether the JSON parses. Vercel's AI Gateway Logs page reports tokens, cost and duration per request. Compare cost per correctly classified message, not only price per token. A low-rate model that needs frequent retries or manual correction may be more expensive for the team than a higher-rate one.
What this announcement does not prove
At the listed rates, a hypothetical 100,000 input tokens and 20,000 output tokens would cost $0.0068 before caching, promotional details or other billing differences. That is arithmetic, not a measured workload. It says nothing about Hy4 Flash's accuracy, latency or usefulness compared with your current model. Keep the same dataset, scoring rubric and privacy checks for both.
SoyJB verification: we checked the official Vercel listing, model ID, date, visible rates, access and limits. We did not make a paid model call or measure classification quality. Review Tencent Cloud's linked data terms before sending personal customer information. Keep a human approval step for outbound responses.
Sources: Vercel's Hy4 Flash model page; Vercel AI Gateway Logs; Tencent official visual identity resources consulted for the cover.